Same Ranking, Different Winner
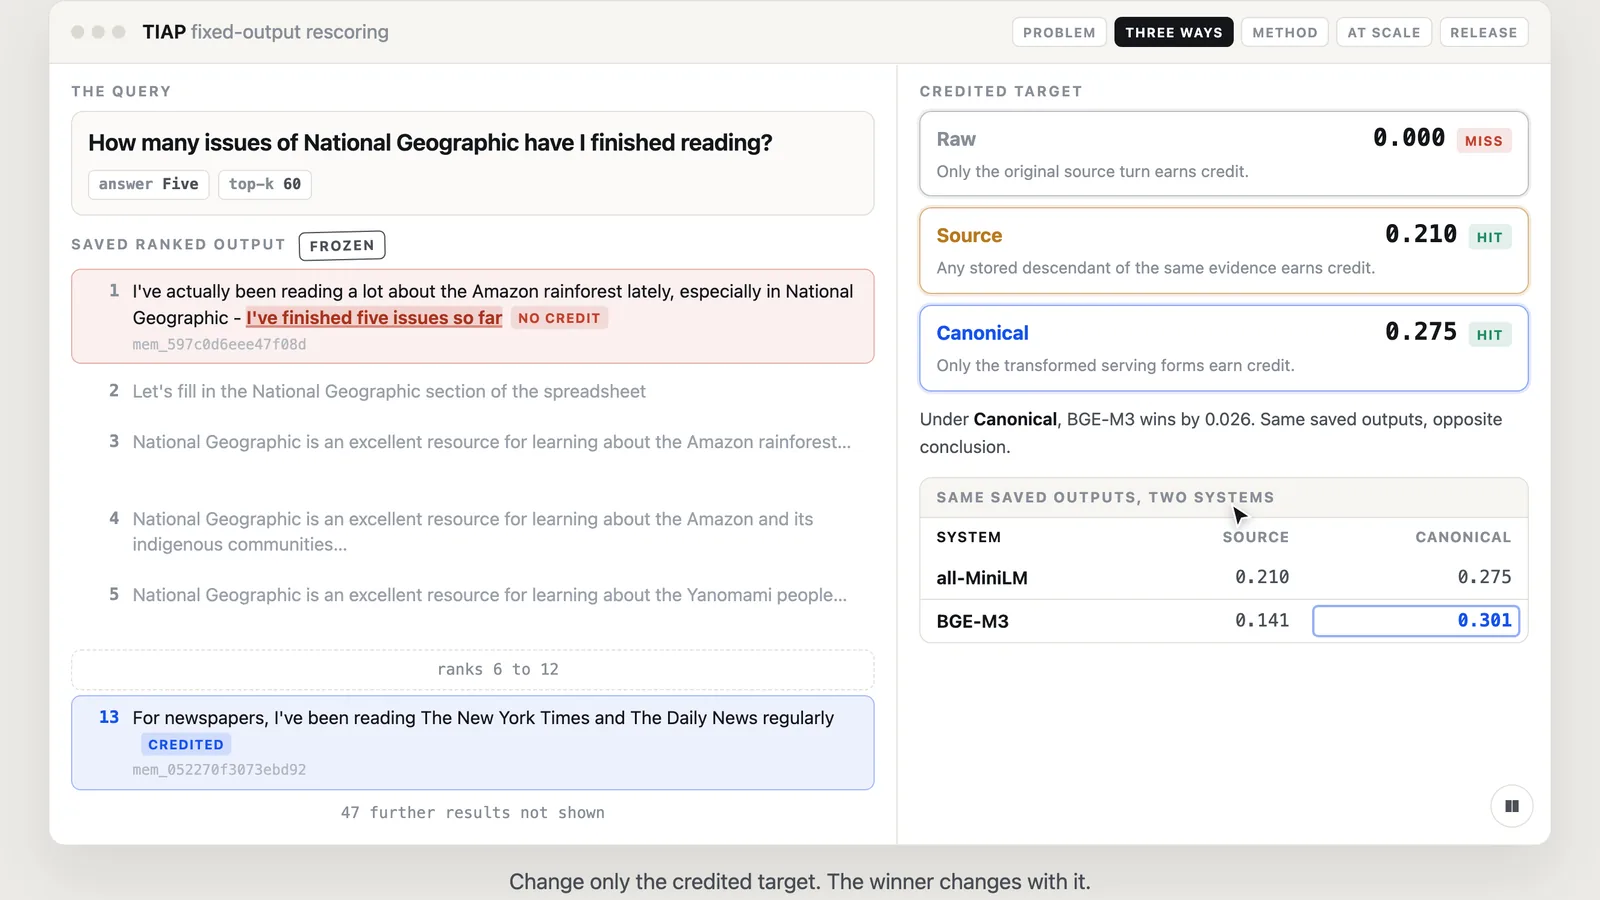
The scoring target a memory benchmark picks can flip which LLM wins, even when the overall ranking looks stable.
We work on how machines see, remember, retrieve, and explain themselves, and on whether the results hold up when you look closely. Please click each project to learn more.
The scoring target a memory benchmark picks can flip which LLM wins, even when the overall ranking looks stable.
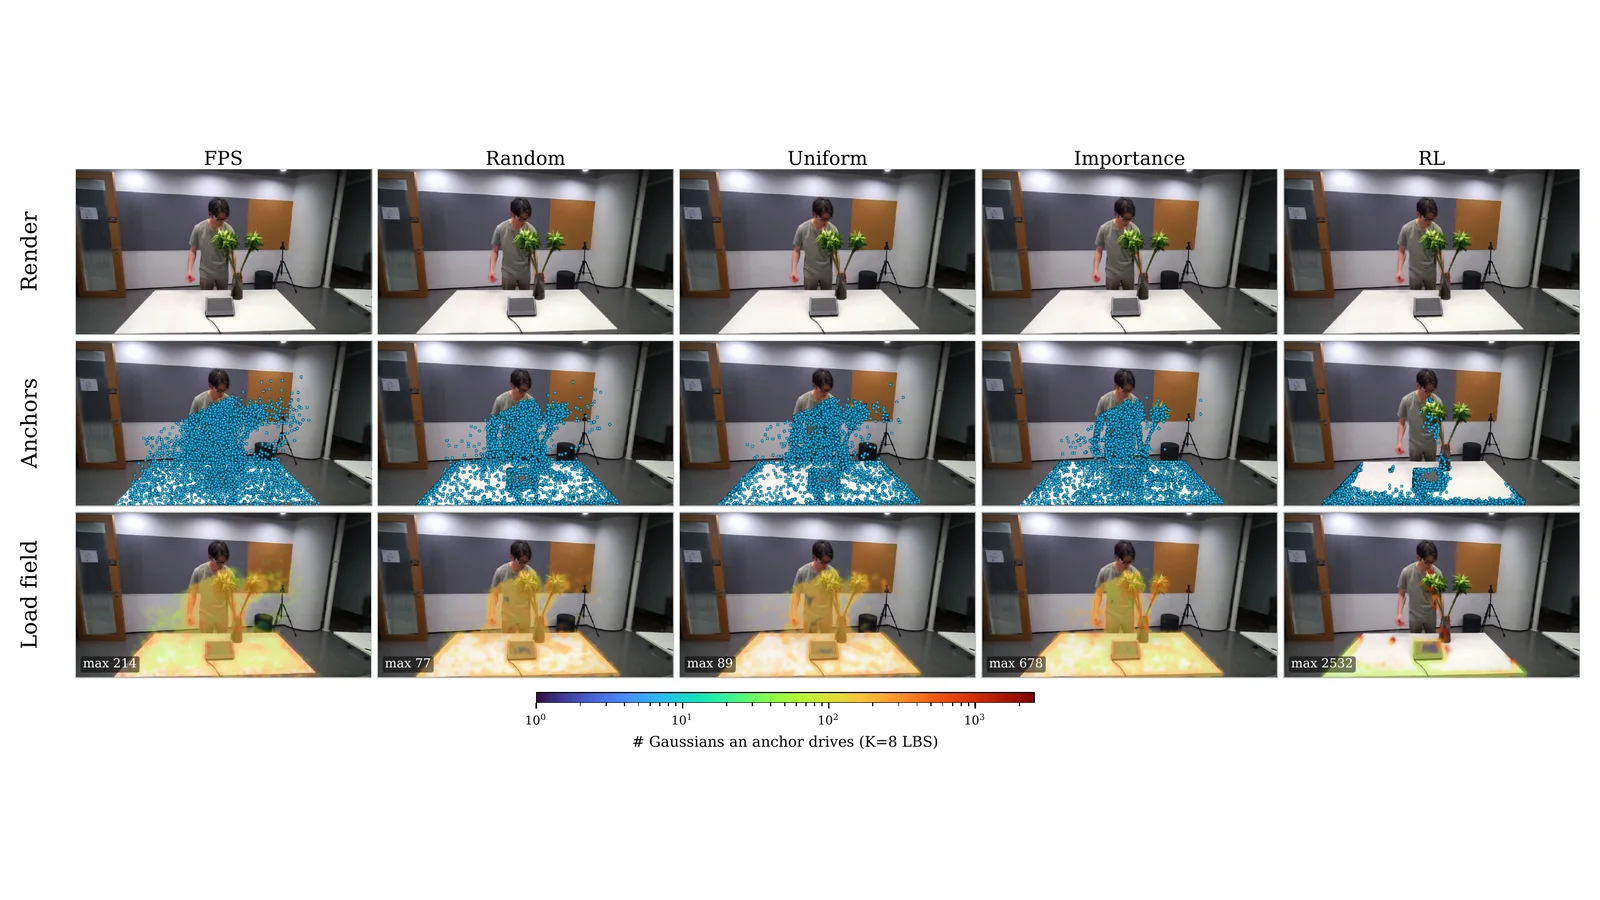
Which Gaussians you pick as anchors barely matters: cheap samplers match the default strategy at deployment budgets, so the standard 8,192-anchor choice over-spends compute.
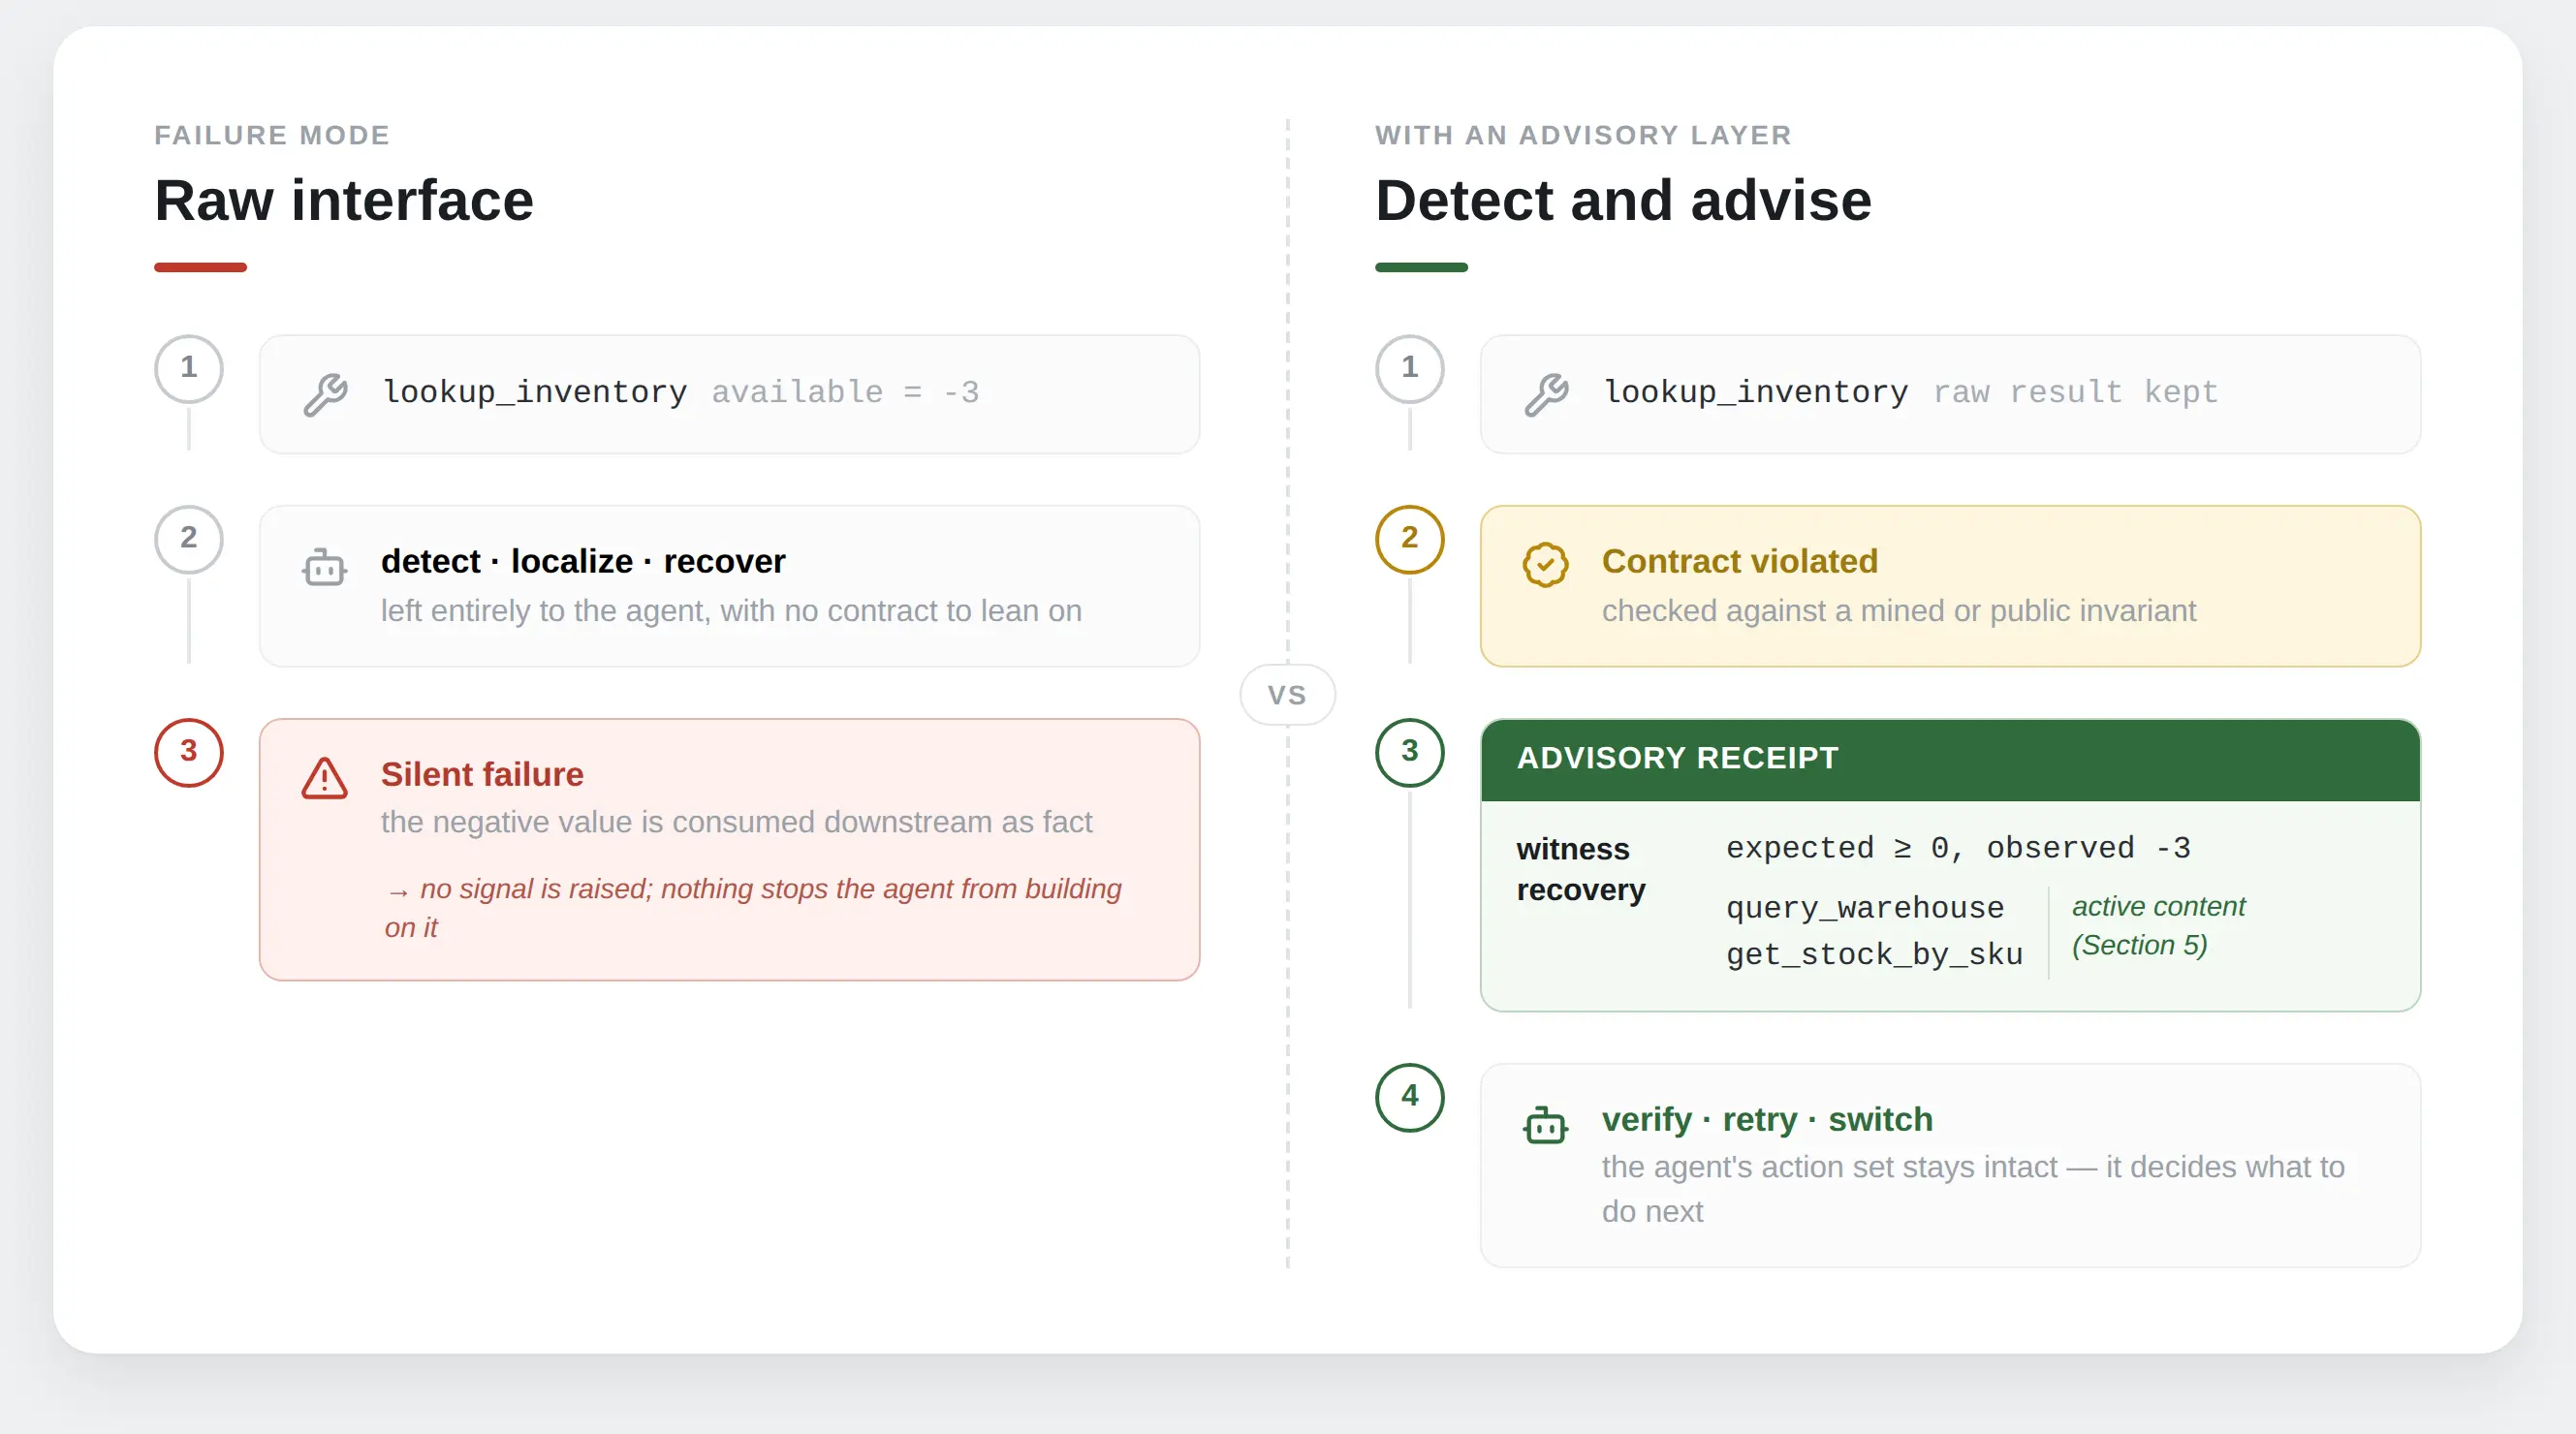
Recovery affordances that let an agent notice and repair tool calls that failed silently.
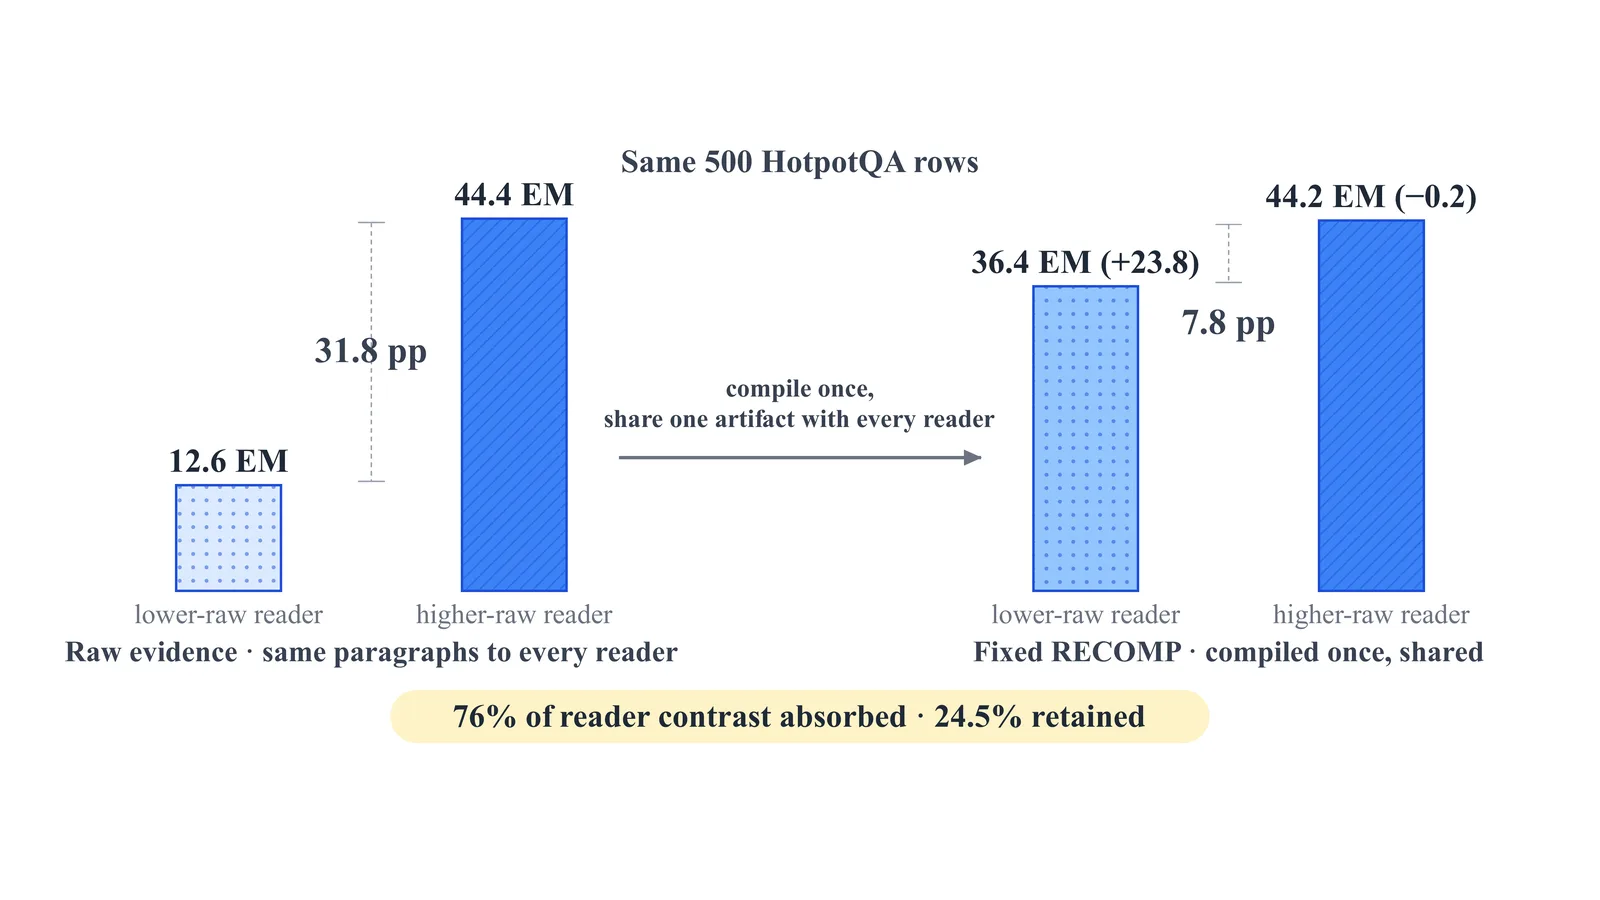
A fixed compression layer in a RAG pipeline collapses the reader-scaling trend that the uncompressed setup shows.
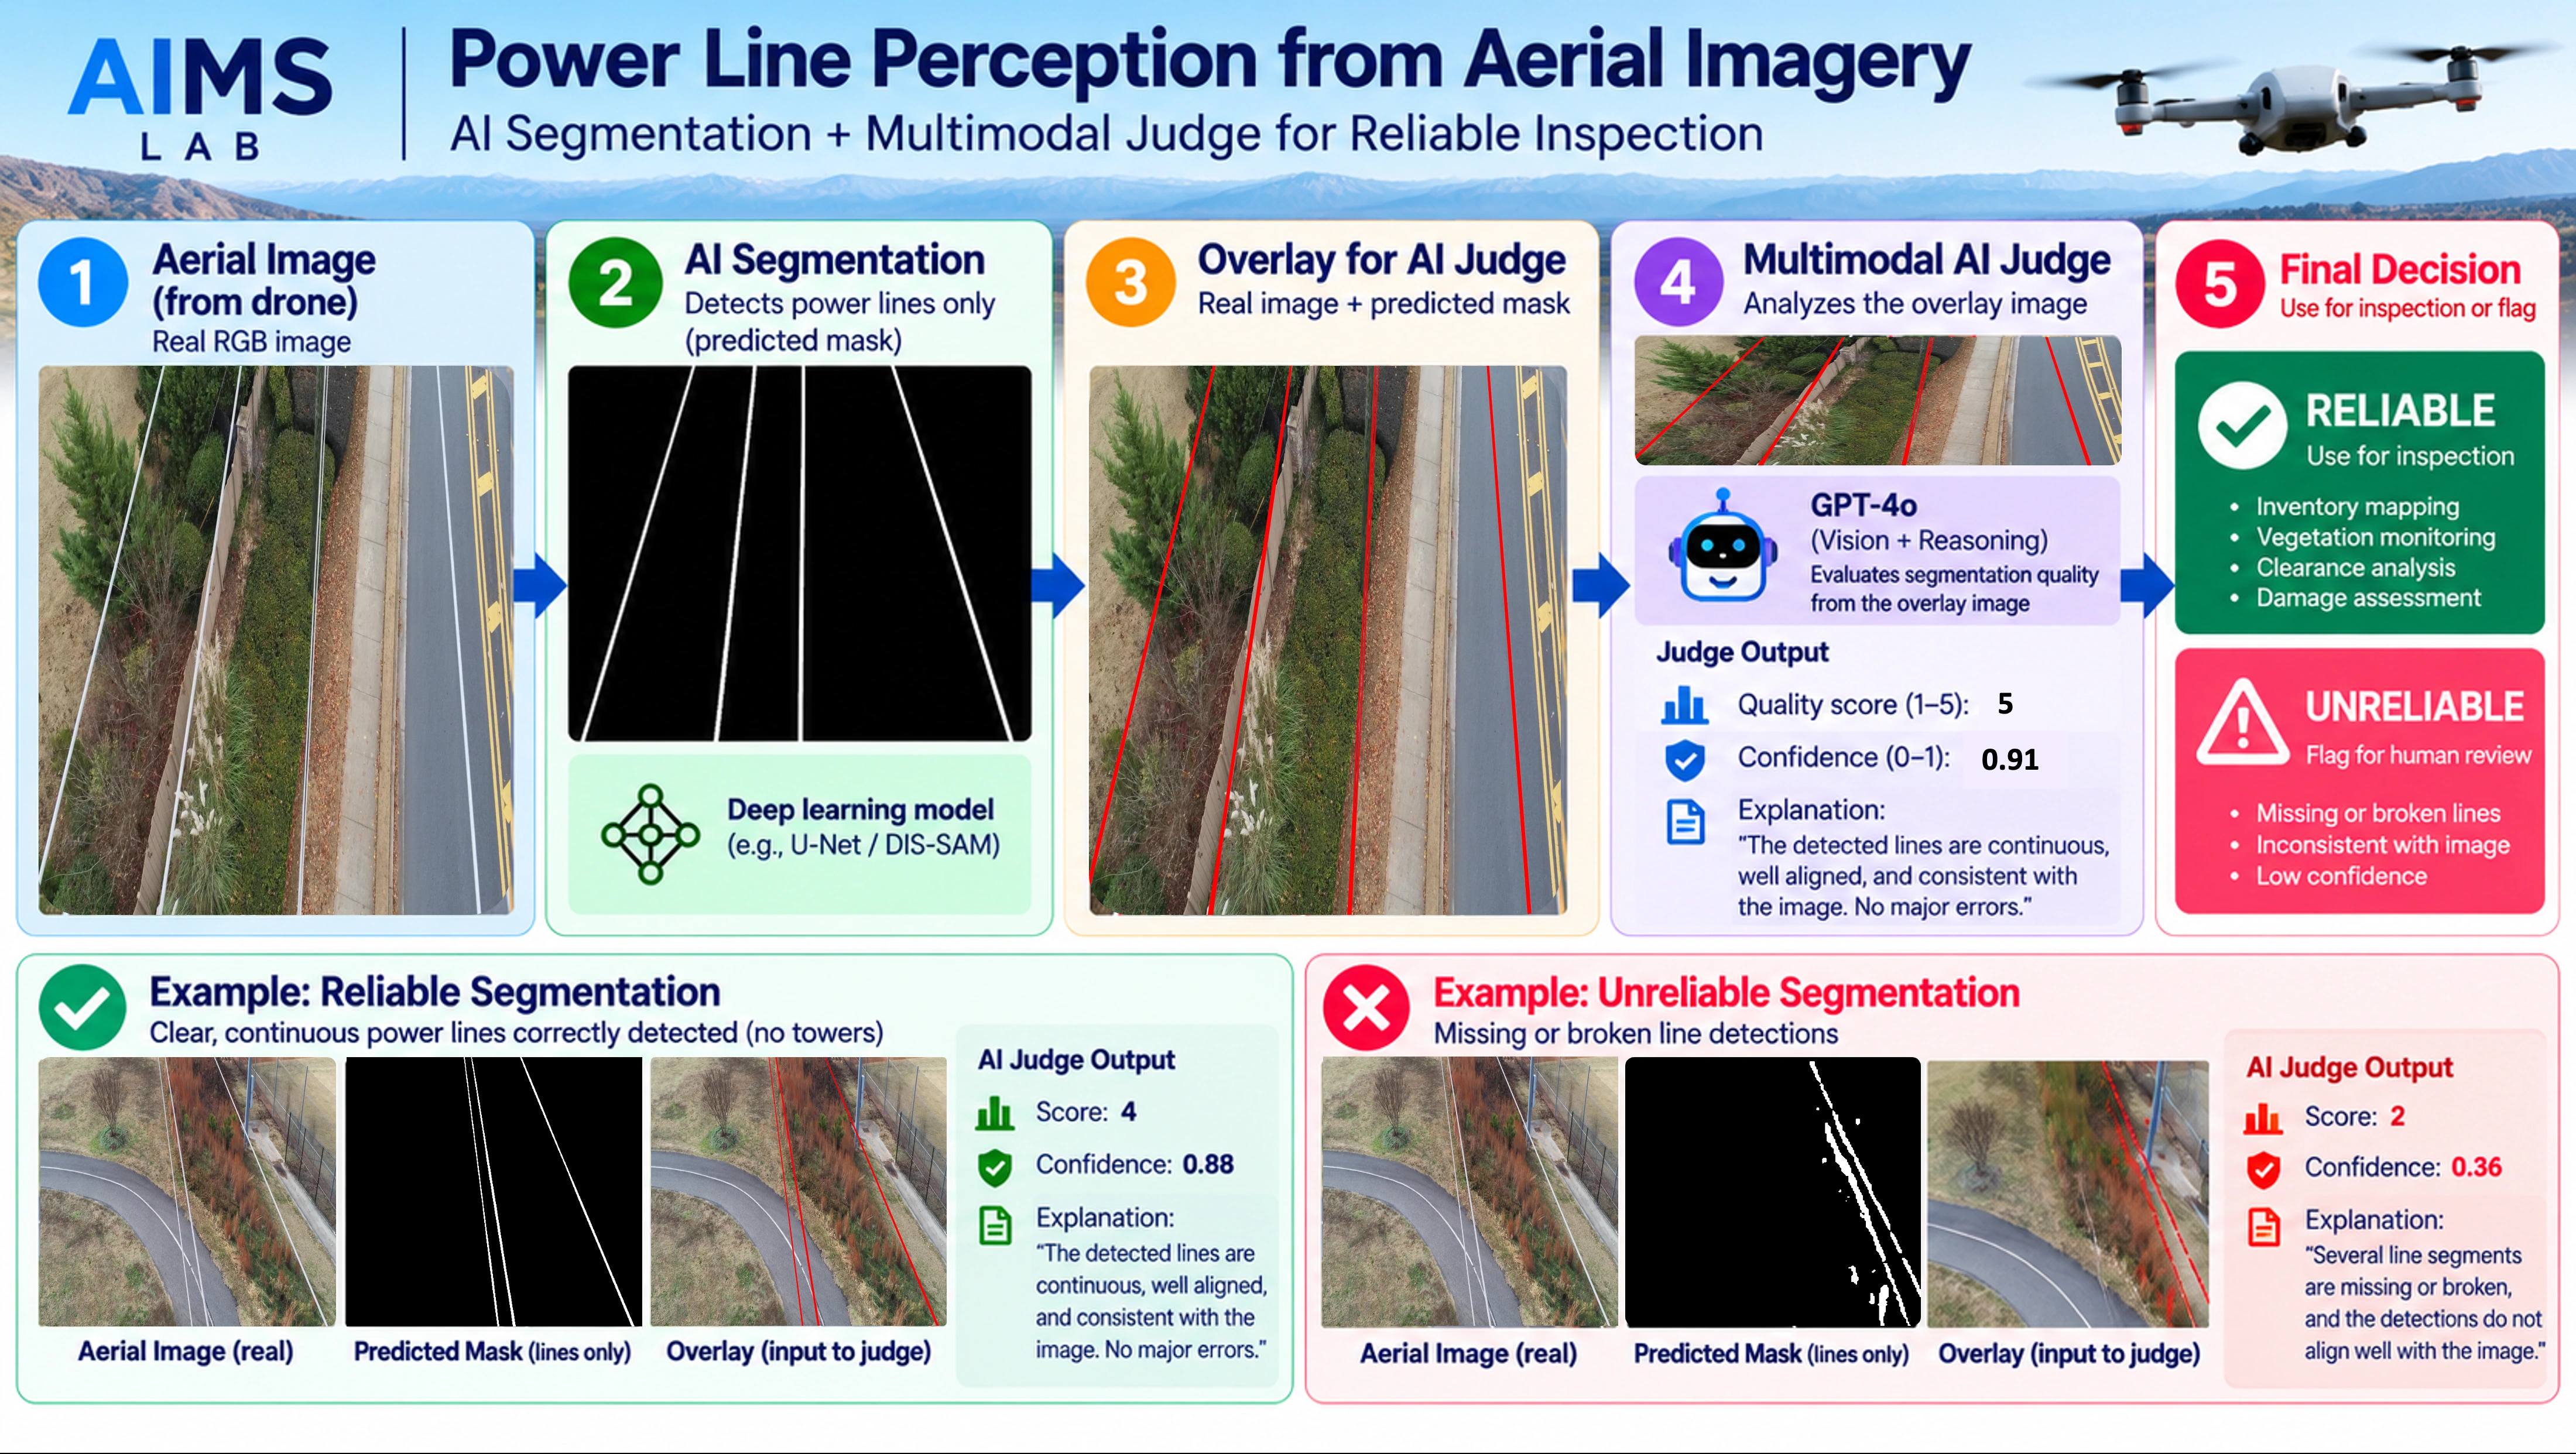
A cross-domain survey of power-line, crack, and retinal-vessel segmentation, from classical pipelines to promptable foundation models.
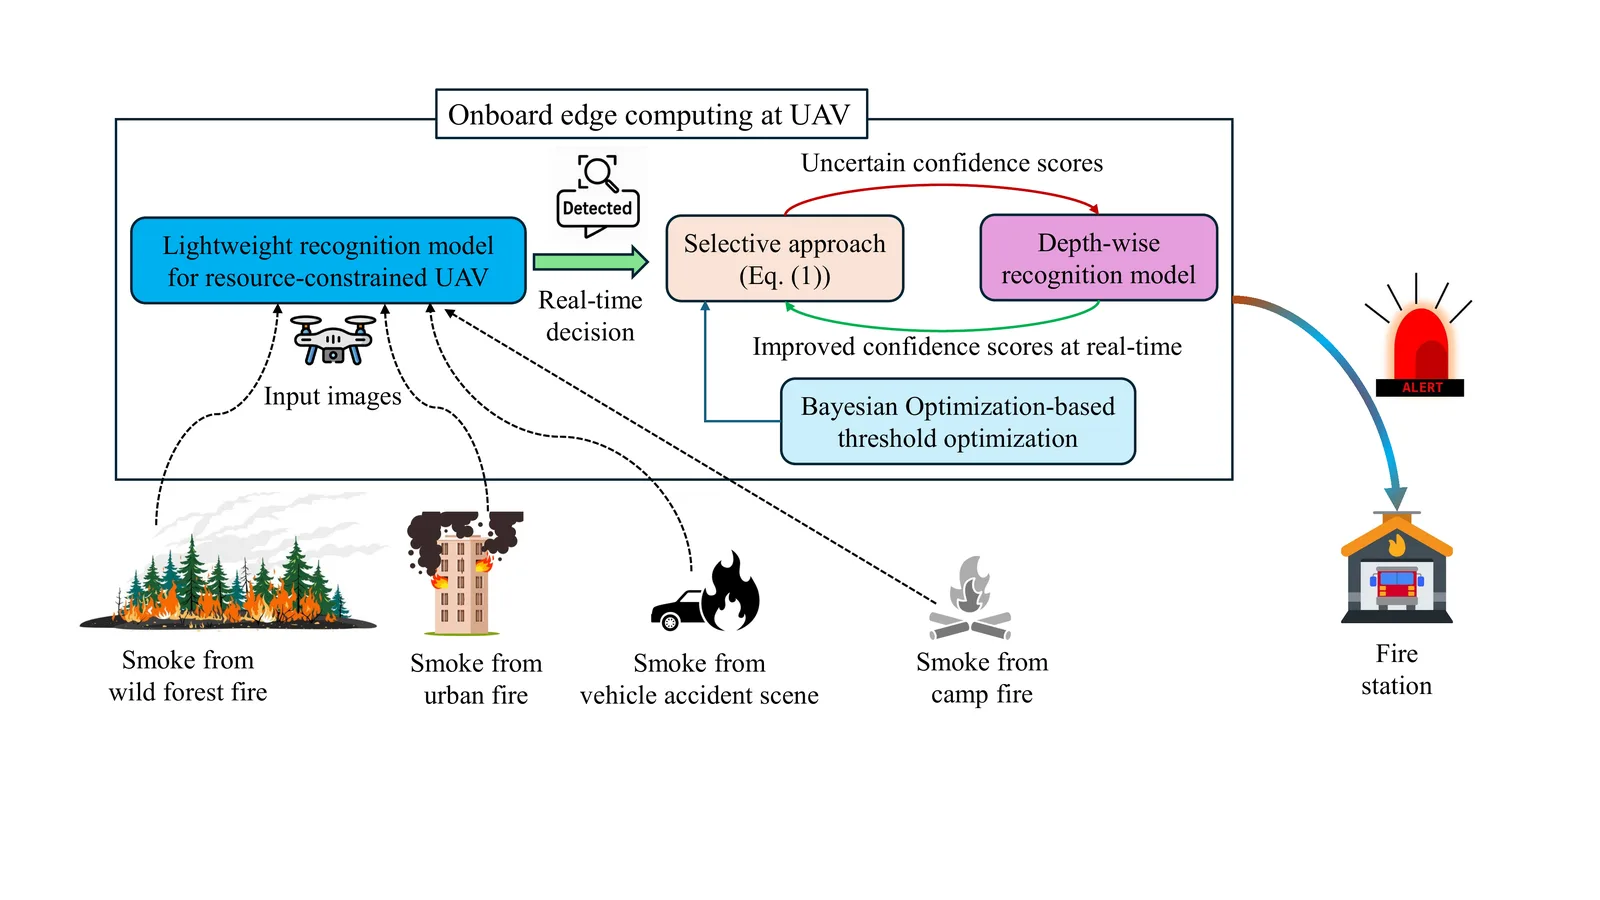
A lightweight CNN screens every frame on the drone and hands only uncertain ones to a stronger model, cutting processing time by up to 56.9%.