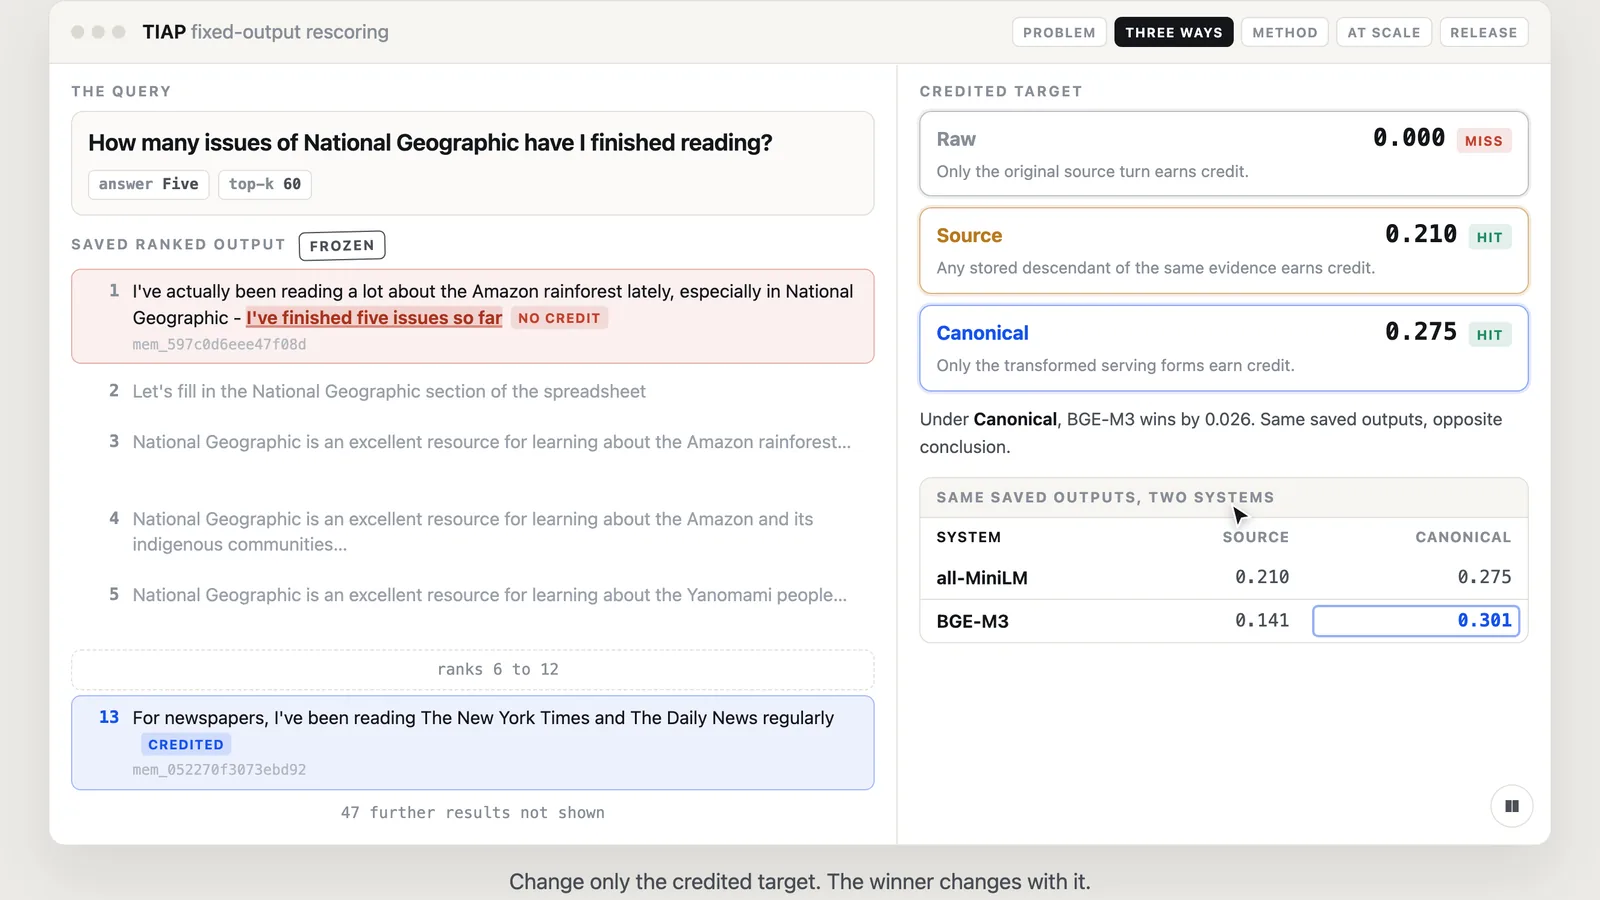
Same Ranking, Different Winner
The scoring target a memory benchmark picks can flip which LLM wins, even when the overall ranking looks stable.
Overview
A conversational-memory benchmark has to decide what it scores: the final answer, the retrieved evidence, or the stored memory itself. That choice is usually treated as a detail of the harness. It is not.
What we found
Holding the models, the data, and the prompts fixed and changing only the scoring target leaves the overall ranking broadly intact while changing which system comes first. A leaderboard that reports one target therefore reports a winner that another target would not have picked.
Walkthrough
One real query, rescored under all three targets, is on the live audit page: the conversation, what it stored, what retrieval returned, and how the verdict moves as the target changes.